Bleep
Find where sensitive speech is, without transcribing what was said.
A small frame-tagging model that reads audio and outputs
(category, start, end) — a spoken digit string here, a
letter-by-letter spelling there — and nothing else. It never produces a
transcript, and it has no mechanism that could: the network takes log-mel
features and emits nine per-frame channels.
STATUS: closed at this problem framing
The oracle arm — a perfect transcript fed to the same text rules — scores …. … At this problem framing the room above the baseline is bounded by that gap — … recall on the test split — and this is the measurement that establishes it.
Retrained to convergence on 2026-10-18. Pre-convergence numbers are kept beside the new ones. These are final; there will not be a third training run.
Where it does not hold
…
Why it was negative before convergence
The training conditions were too mild
…
The model was badly undertrained
1500 steps, batch 4, ~1.8 epochs over 9.15 hours — 70 minutes on one consumer GPU. The validation loss recorded during that run (0.218, 0.200, 0.191, 0.203, 0.192, 0.183) was measured on freshly re-sampled crops, rose once, and ended under a learning rate already annealed to 2% of its peak: a stopped run, not a converged one. (This page previously said the loss was "still falling monotonically"; that was not accurate.) The retrain ran to a stopping rule fixed and hashed before it started, and stopped by that rule.

One directional hint
…
What is complete and load-bearing
…
Timeline viewer
Real utterances: the first ones from test (conditions the
model was trained on) and from test_heldout_v2 (conditions it
never saw). Ground truth against what each detector actually found, at the
operating points the benchmark reports. The pre-convergence model has its own
lane.
No audio is shipped. These recordings were rendered with the macOS system voices, which are licensed for use and not for republication as a corpus. What you see is a downsampled amplitude envelope — a few hundred numbers per utterance, enough to draw a waveform, not enough to reconstruct speech.
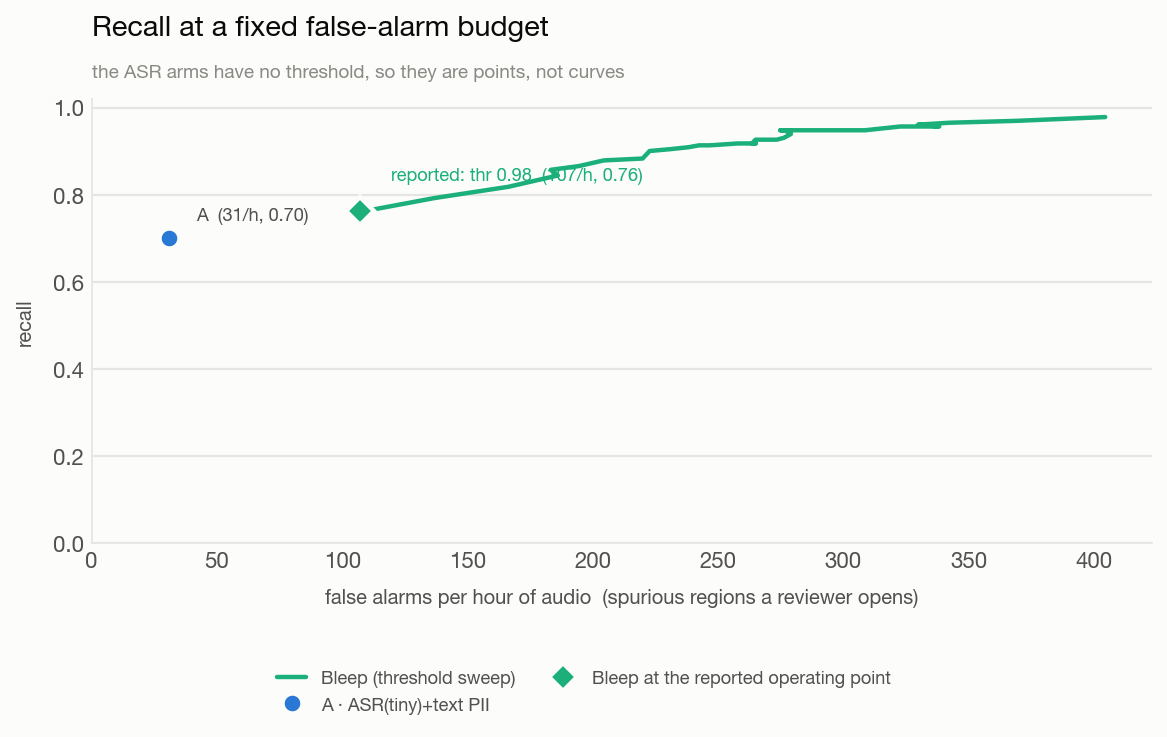
Recall by degradation condition

Recall by category
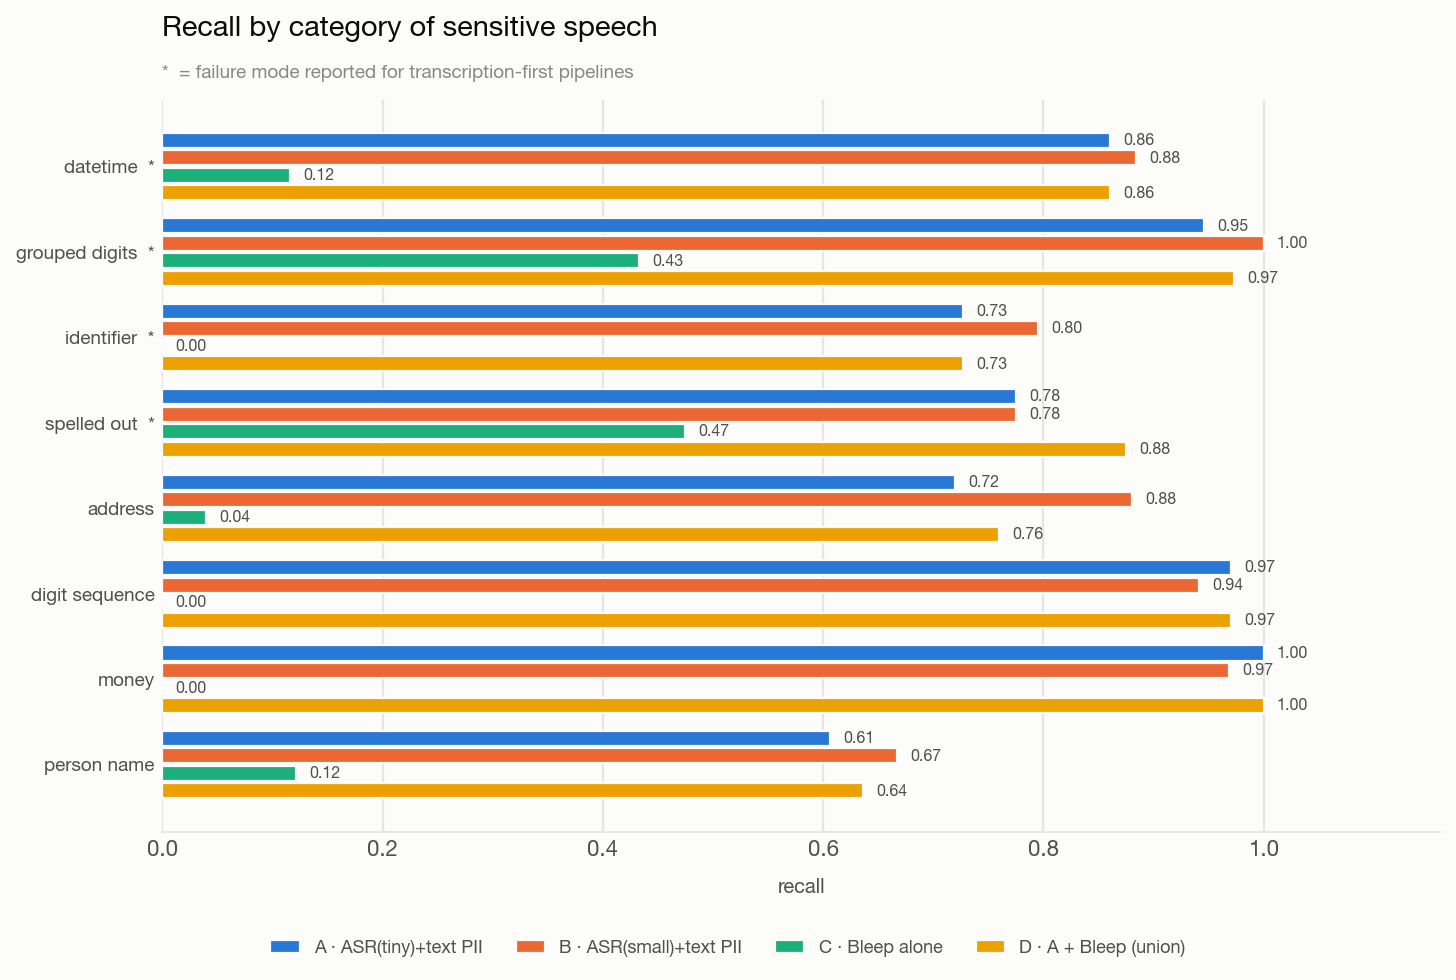
figures/pre-convergence/.What this is not
Not a redaction guarantee. Even on the conditions it was trained on it misses about one region in ten; on conditions it was not, roughly one in five to one in four, while raising several times the baseline's false alarms. An empty result means “nothing was flagged”, never “nothing is there”.
Not a replacement for your ASR-based detector. It beats the baseline only on the degradation types it was trained on. It is designed for union mode, and the union is verified never to drop a region the existing detector found — zero violations on every utterance of all three evaluation splits.
Not trained on real audio. Every recording is synthetic. No real call, no clinical recording, nothing derived from either, at any stage. That is also a limitation: TTS speech is far easier to transcribe than conversation, which is part of why the baseline looks so strong here.
English only. Japanese generators exist in the code but are not benchmarked.
…
Apache-2.0. Negative results are cheap to hide and expensive to rediscover; closed projects are worth closing in writing.